Gemini 2.5 Pro Pricing After the 1 December Reroute
On 1 December 2026 Google stops serving Gemini 2.5 Pro under its own name. Google’s deprecations page says that from that date “all API requests to gemini-2.5-pro will automatically route to gemini-3.8-flash and be billed at Gemini 3.8 Flash rates.” Gemini 2.5 Flash gets the same treatment on the same day, rerouted to Gemini 3.5 Flash-Lite. Your code keeps working and no error appears. The model behind your chatbot changes, and so does the price.
That makes this a pricing change more than a shutdown. Gemini 2.5 Pro pricing today is $1.25 per million input tokens and $10 per million output tokens. From 1 December the same requests bill at 3.8 Flash’s $0.75 / $3.75. Then, on 1 January 2027, 3.8 Flash itself doubles to $1.50 / $7.50.
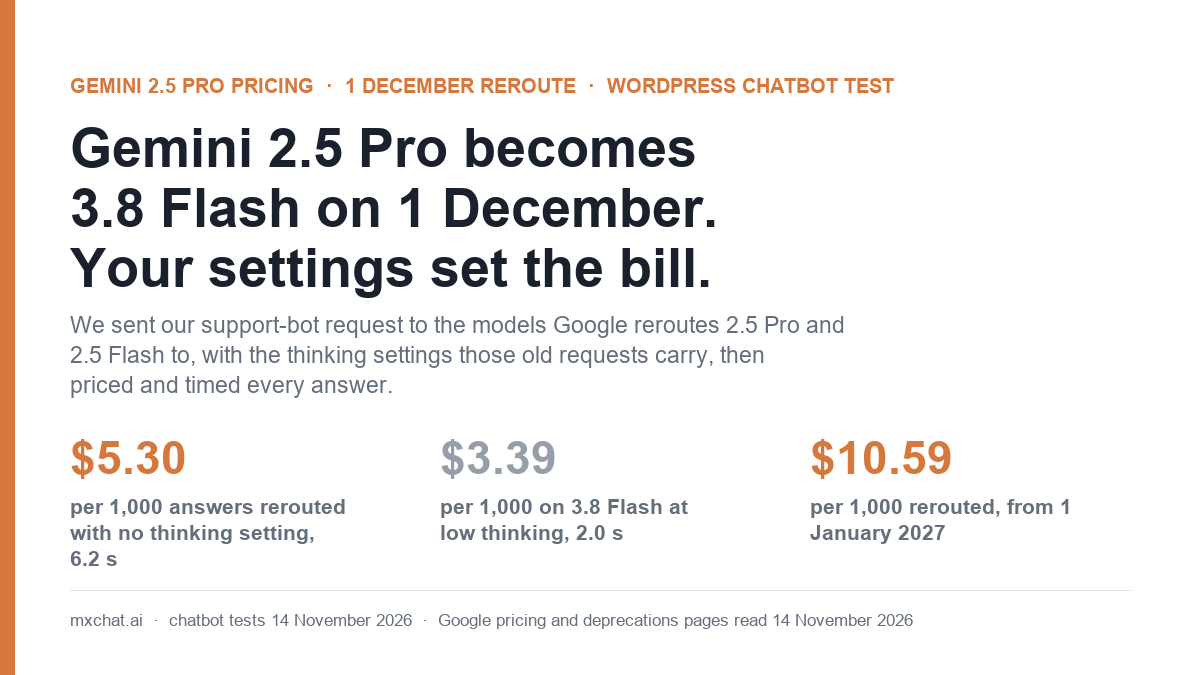
On 14 November 2026 we sent our own support-bot request from our WordPress server to the models those calls will land on, with the settings a rerouted request will carry. The short answer: a 2.5 Pro bot that sends no thinking setting, which includes every MxChat bot on 2.5 Pro, will run on 3.8 Flash at its default thinking. That cost $5.30 per 1,000 answers with a median of 6.2 seconds. Choose 3.8 Flash yourself and MxChat sends thinking at low: $3.39 per 1,000 answers in 2.0 seconds. From January those figures become $10.59 and $6.79. All 40 answers were correct.
What changes on 1 December 2026
Both reroutes are listed on Google’s Gemini API deprecations page and on the pricing page, which we read on 14 November 2026. Prices are per million tokens on the Standard paid tier, for prompts up to 200,000 tokens. Output prices include thinking tokens.
| Model ID you send | Price until 30 Nov | Served by from 1 Dec | Price from 1 Dec | Price from 1 Jan 2027 |
|---|---|---|---|---|
gemini-2.5-pro | $1.25 / $10.00 | Gemini 3.8 Flash | $0.75 / $3.75 | $1.50 / $7.50 |
gemini-2.5-flash | $0.30 / $2.50 | Gemini 3.5 Flash-Lite | $0.30 / $2.50 | $0.30 / $2.50 |
gemini-2.5-flash-lite | Not deprecated | No change | No change | No change |
A few details in the small print matter for a chatbot:
- Long prompts: 2.5 Pro charges $2.50 / $15 above 200,000 input tokens. 3.8 Flash has no long-prompt surcharge, so very long knowledge-base prompts get a bigger cut.
- Cached input falls from $0.125 on 2.5 Pro to $0.075 on 3.8 Flash, then rises to $0.15 in January.
- Google Search grounding moves to the Gemini 3 terms: 5,000 free requests a month shared across Gemini 3 and newer models, then $14 per 1,000, against 1,500 free a day and $35 per 1,000 grounded prompts on 2.5 Pro.
- New users are already locked out. When we called
gemini-2.5-proandgemini-2.5-flashwith our site’s paid key on 14 November, both returned HTTP 404: “no longer available to new users.” Only accounts that used the models before keep access until the reroute.
How we tested it
The request was the one our own MxChat support bot sends: the site’s system prompt plus four knowledge-base passages of about 4,000 characters each, about 4,130 input tokens in total, followed by a visitor question. We used four real questions from our support inbox: WooCommerce order lookups, whether Pinecone is required for the knowledge base, human handoff to Slack or Telegram, and which API keys and models can be used.
- Calls went to the Gemini API
generateContentendpoint directly, with our site’s paid key, from our WordPress server in the US. No streaming, default temperature. - What we could not test: Gemini 2.5 Pro and 2.5 Flash themselves. Our key is treated as a new user and gets a 404, so there is no measured “before” in this article. Where we compare with 2.5 Pro, it is the measured tokens priced at 2.5 Pro’s list rate, labelled as such.
- Eight setups: Gemini 3.8 Flash with no thinking setting, with
thinkingBudget: -1(dynamic), withthinkingBudget: 128and withthinkingLevel: low; Gemini 3.5 Flash-Lite with no setting, withthinkingBudget: -1and withthinkingBudget: 0; and Gemini 3.1 Pro preview at low. - The two “no setting” rows and 3.8 Flash at low ran twice (8 answers each), the rest once (4 answers each). 40 answers plus one rejected request, and about 40 short probe calls. The whole test cost about $0.18.
- Cost is the token counts Google returned, priced at the list rate for the model Google said it served, with no cache discount. Every answer was checked against our documentation for the one fact each question turns on.
One limit to keep in mind: we sent these settings straight to 3.8 Flash and 3.5 Flash-Lite. Google has not said whether a request addressed to gemini-2.5-pro after 1 December is handled exactly like the same request sent to gemini-3.8-flash. We will repeat the test through the old model IDs on 1 December and update this page.
What a rerouted bot costs per 1,000 answers
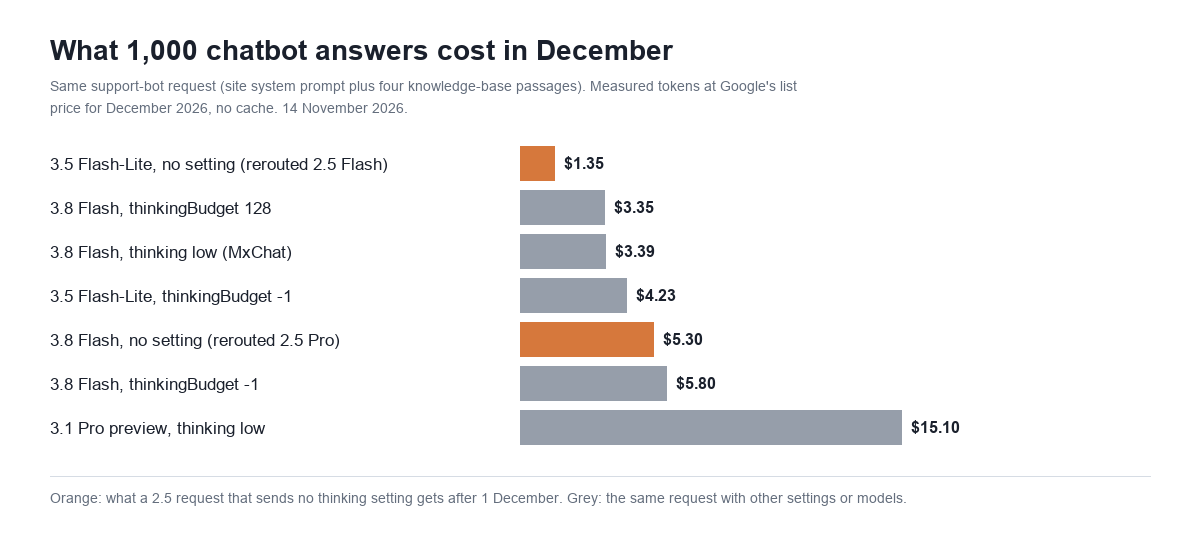
| Setup | Per 1,000 answers (Dec) | Median time | Thinking tokens per answer | Answer words |
|---|---|---|---|---|
| 3.5 Flash-Lite, no thinking setting (rerouted 2.5 Flash) | $1.35 | 0.94 s | 0 | 29 |
3.8 Flash, thinkingBudget: 128 | $3.35 | 2.59 s | 0 | 48 |
| 3.8 Flash, thinking low (what MxChat sends for 3.8 Flash) | $3.39 | 2.04 s | 0 | 56 |
3.5 Flash-Lite, thinkingBudget: -1 | $4.23 | 3.74 s | 1,144 (772 to 1,613) | 35 |
| 3.8 Flash, no thinking setting (rerouted 2.5 Pro) | $5.30 | 6.17 s | 518 (259 to 660) | 50 |
3.8 Flash, thinkingBudget: -1 | $5.80 | 6.33 s | 649 (460 to 999) | 51 |
| 3.1 Pro preview, thinking low | $15.10 | 6.30 s | 508 (371 to 619) | 48 |
3.5 Flash-Lite, thinkingBudget: 0 | HTTP 400, “Request contains an invalid argument” | |||
Input tokens were the same on every model, about 4,130 per request, so the spread comes from output and thinking. On 3.8 Flash with no setting, input was $3.10 of the $5.30 and thinking about $1.94. At low, thinking disappeared and the answer was the same length.
Google also applied its implicit cache to repeat passes, as it does for any prompt that starts with a recently seen prefix. With that discount the rerouted 2.5 Pro row billed $4.59 per 1,000 and 3.8 Flash at low $2.69. The table uses the uncached figure because a quiet support bot may not send the same prefix often enough to hit the cache.
Your thinking setting decides the bill
A reroute changes the model, not the request. Whatever your code sends to gemini-2.5-pro today is what 3.8 Flash will receive on 1 December, and 3.8 Flash reads three common 2.5-era settings very differently:
- No thinking setting at all. 2.5 Pro decides how much to think on its own, so plenty of code never sets anything. On 3.8 Flash that meant its default: about 520 thinking tokens per answer, $5.30 per 1,000 and 6.2 seconds, with one answer taking 18.6 seconds.
thinkingBudget: -1(dynamic, the explicit form of the same thing) thought a little more: about 650 tokens and $5.80.thinkingBudget: 128, the lowest budget 2.5 Pro accepts, switched thinking off completely on 3.8 Flash: zero thinking tokens and $3.35, practically the same as thinking at low.
The cheapest way through the reroute is therefore not to wait for it. Change the model ID to gemini-3.8-flash yourself and send thinkingLevel: low. On these four questions the answers were as correct as the default-thinking ones and arrived three times faster.
Speed: the reroute is slower than choosing the model yourself
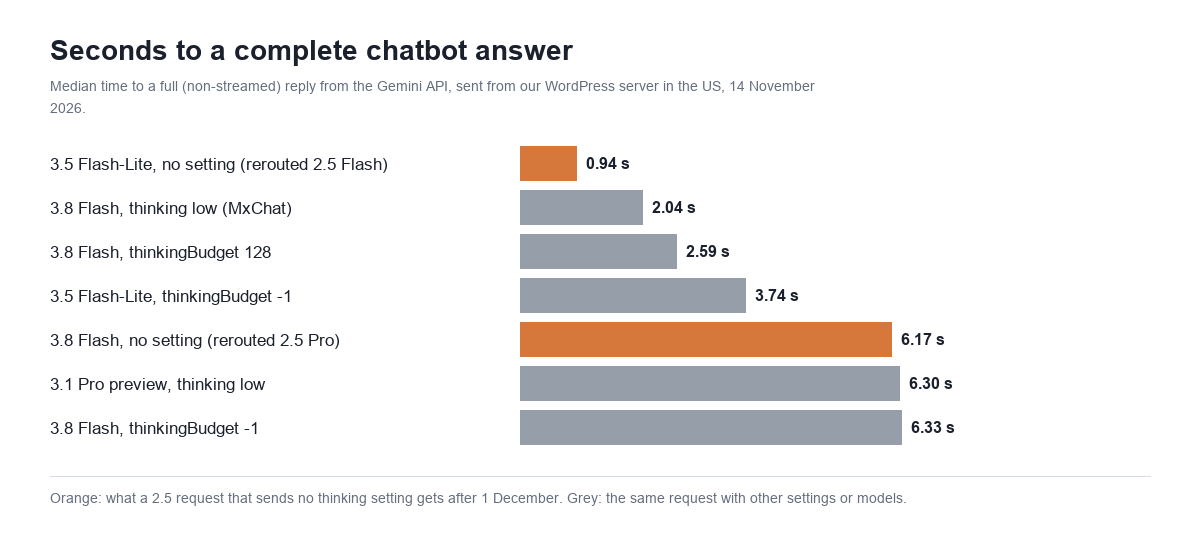
Default thinking costs time as well as money. The rerouted 2.5 Pro setup had a median of 6.17 seconds and a slowest answer of 18.57 seconds. 3.8 Flash at low had a median of 2.04 seconds and never went above 2.16. For a chat window that waits for the full reply, that is the difference between an answer that feels instant and one where the visitor starts typing again.
3.5 Flash-Lite, where 2.5 Flash requests land, was the fastest model we tested: a median of 0.94 seconds with no thinking setting.
The 2.5 Flash reroute: same price, different model
Gemini 2.5 Flash and Gemini 3.5 Flash-Lite share a rate card, $0.30 input and $2.50 output, so Google can say requests are “billed at Gemini 3.5 Flash-Lite rates” without any price change. What changes is the model, and two things showed up in our test.
- Shorter answers. With no thinking setting, 3.5 Flash-Lite spent no thinking tokens and averaged 29 words per answer, against about 50 from 3.8 Flash. All eight answers were correct, but they were terse. If your bot’s replies were written to sound helpful rather than minimal, check a few after 1 December.
thinkingBudget: 0was rejected. On 2.5 Flash, a budget of 0 is the standard way to turn thinking off, and a lot of chatbot code sets it for speed. Sent to 3.5 Flash-Lite, the same request returned HTTP 400 “Request contains an invalid argument” on the probe and again on the real support-bot request. If Google passes the setting through unchanged on 1 December, a 2.5 Flash bot set up this way would start failing instead of quietly getting cheaper. We could not test the reroute itself before the date, so treat this as a risk to check, not a confirmed outage.
The opposite setting is expensive. With thinkingBudget: -1, 3.5 Flash-Lite thought for about 1,140 tokens per answer, more than 3.8 Flash did, and cost $4.23 per 1,000 answers, three times its no-setting cost. Our Gemini Flash-Lite pricing comparison has more on the 2.5 and 3.5 Flash-Lite models.
January 2027: the rerouted price doubles
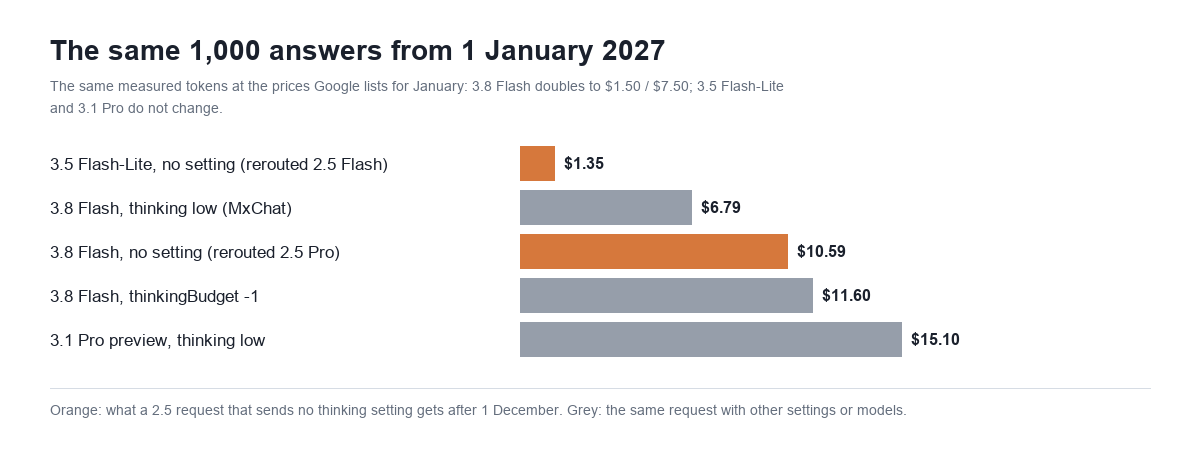
The 3.8 Flash rate that 2.5 Pro requests inherit is an introductory price. Google’s pricing page lists $0.75 / $3.75 “through December 31, 2026” and $1.50 / $7.50 “starting January 1, 2027”. Gemini 3.5 Flash-Lite has no scheduled change.
| Setup | Per 1,000 answers in December | From 1 January 2027 |
|---|---|---|
| 3.5 Flash-Lite, no thinking setting (rerouted 2.5 Flash) | $1.35 | $1.35 |
| 3.8 Flash, thinking low | $3.39 | $6.79 |
| 3.8 Flash, no thinking setting (rerouted 2.5 Pro) | $5.30 | $10.59 |
3.8 Flash, thinkingBudget: -1 | $5.80 | $11.60 |
| 3.1 Pro preview, thinking low | $15.10 | $15.10 |
So the cut is real but short. A rerouted 2.5 Pro bot gets one cheap month and then pays twice that from January, unless thinking is turned down.
Against what 2.5 Pro cost
We could not run 2.5 Pro, so here is the comparison we can make honestly. At 2.5 Pro’s list price, the measured 4,130 input tokens alone cost $5.17 per 1,000 answers. Add a 70-token answer at $10 per million and the total is about $5.85 per 1,000 answers, before any thinking. 2.5 Pro cannot switch thinking off (its lowest budget is 128 tokens), so a real 2.5 Pro bill per answer was higher than that floor. This assumes 2.5 Pro counts our prompt in about the same number of tokens as the Gemini 3 models, which we could not check.
- In December, every 3.8 Flash setup we measured ($3.35 to $5.80) is at or below that zero-thinking floor. The reroute saves money in December for every 2.5 Pro bot.
- From January, 3.8 Flash at default thinking ($10.59) is well above the floor. Whether it costs more than your old 2.5 Pro bill depends on how much your bot thought on 2.5 Pro. Gemini reports this as
thoughtsTokenCountin each response’s usage data, so your own logs can answer it. 3.8 Flash at low ($6.79) is within about 16% of the floor.
What to do before 1 December
- Find every place that names a 2.5 model. Chatbot settings, content generators, form plugins and custom code can each hold their own model ID. Search for
gemini-2.5-proandgemini-2.5-flash(but notgemini-2.5-flash-lite, which is not affected). - Replace
gemini-2.5-prowithgemini-3.8-flashand set thinking to low. That was the cheapest 3.8 Flash setup that answered every question correctly, and the fastest. If you need Pro-level reasoning for something other than support chat, test that work separately. - Replace
gemini-2.5-flashdeliberately. 3.5 Flash-Lite at the same price is the like-for-like choice. RemovethinkingBudget: 0first, since 3.5 Flash-Lite rejected it. Or pick 3.8 Flash at low if you want longer answers, at about 2.5 times the cost. - Don’t jump to 3.1 Pro by reflex. Google’s 404 message recommends
gemini-3.1-pro-previewto anyone still calling 2.5 Pro. For support chat it cost $15.10 per 1,000 answers at low thinking, 4.5 times 3.8 Flash at low, with no gain in correctness on these questions. - Budget for January. Whatever 3.8 Flash costs you in December, double it from 1 January.
If you are weighing other Gemini models while you change settings, our Gemini 4 Hydrogen pricing test and Gemini 4 Carbon pricing test ran the same request. Our Gemini 3.8 Flash pricing article covers its thinking levels in more detail. For the same problem on the OpenAI side, where GPT-5 and GPT-5 mini shut down on 11 December, see our guide to OpenAI model deprecations.
Gemini 2.5 Pro in MxChat
We checked MxChat 3.2.28 on our own site. The plugin lists Gemini 2.5 Pro, 2.5 Flash and 2.5 Flash-Lite as legacy models: a site that already uses one keeps it, but new picks are steered elsewhere. For the 2.5 models (and for 3.5 Flash-Lite) the plugin sends no thinking setting, so a 2.5 Pro bot in MxChat will get the $5.30 “no thinking setting” row above after 1 December, not the $3.39 row.
To get the cheaper row, open the chatbot settings and choose Gemini 3.8 Flash, the plugin’s recommended Gemini model. MxChat then sends thinkingLevel: low automatically. The picker’s note on the legacy 2.5 Pro entry suggests Gemini 3.1 Pro instead. On our measurement that is the most expensive option in this test, so for a support bot pick 3.8 Flash. Setup steps for Gemini keys are in the MxChat documentation, and MxChat Pro adds the WooCommerce order lookups and human handoff our test questions asked about.
Frequently asked questions
Is Gemini 2.5 Pro being shut down?
Not as a hard shutdown. From 1 December 2026, requests to gemini-2.5-pro are routed to Gemini 3.8 Flash and billed at 3.8 Flash rates. It is already unavailable to new API users and in Google AI Studio.
What is Gemini 2.5 Pro pricing until then?
$1.25 per million input tokens and $10 per million output tokens for prompts up to 200,000 tokens, and $2.50 / $15 above that. Thinking tokens are billed as output. Cached input is $0.125.
Will my bill go up or down on 1 December?
Down, per token: 3.8 Flash costs $0.75 / $3.75 until 31 December. From 1 January 2027 it costs $1.50 / $7.50. Per answer, it depends on thinking. In our test the rerouted request cost $5.30 per 1,000 answers with no thinking setting and $3.39 at low.
What happens to Gemini 2.5 Flash?
From 1 December, requests are routed to Gemini 3.5 Flash-Lite at the same $0.30 / $2.50 price. In our test answers came back faster and shorter. A request with thinkingBudget: 0 was rejected by 3.5 Flash-Lite, so remove that setting before the date.
Is Gemini 2.5 Flash-Lite affected?
No. Google’s page says gemini-2.5-flash-lite is not deprecated.
Should I move from Gemini 2.5 Pro to Gemini 3.1 Pro?
Not for a support chatbot on our numbers. 3.1 Pro preview at low thinking cost $15.10 per 1,000 answers against $3.39 for 3.8 Flash at low, and both answered every question correctly.
Do I need to change anything if I do nothing?
Nothing breaks for 2.5 Pro: the reroute is automatic. But your bot will run on 3.8 Flash at whatever thinking your code sends, and its price doubles on 1 January. Changing the model ID and thinking setting yourself was cheaper and faster in every comparison we ran.
Prices from Google’s Gemini API pricing and deprecations pages, read 14 November 2026. Chatbot tests run 14 November 2026 from mxchat.ai’s server with a paid Gemini API key; 40 answers, about $0.18 in API cost.