
Together AI Pricing: 6 Open Models Tested on a Chatbot
Together AI pricing for serverless models is per token, and for most popular open-weight models it is exactly the model maker’s own list price. On 19 October 2026 Together charged $0.30 per million input tokens and $1.20 output for DeepSeek V4.1 Flash, $1.40 and $4.40 for GLM-5.3, $0.15 and $0.50 for GLM-5.3 Flash, $0.30 and $1.20 for MiniMax M3, and $3.00 and $15.00 for Kimi K3. Every one of those matches the maker’s own rate card. The exception is Llama 3.3 70B at $1.04 in and $1.04 out, which is ten times what the cheapest host charges for it.
Those are per-token prices. A chatbot pays per answer, so we measured that. On 19 October 2026 we sent the same WordPress chatbot request to six open-weight models on Together AI and on the model maker’s own API or another host, from our production server: 96 streamed calls across 16 routes. One route returned rate-limit errors on every call, which left 90 answers. Together AI was the fastest host we tried for all six models, and on five of them it cost the same per answer as the maker’s own endpoint. DeepSeek V4.1 Flash on Together answered in 0.76 seconds and cost $0.73 per 1,000 answers as billed. Cheaper hosts exist for every model we tested. On Llama 3.3 70B the gap was $4.32 against $0.42 per 1,000 answers. All 90 answers were correct.
- Together charges maker list price. On DeepSeek V4.1 Flash, GLM-5.3, GLM-5.3 Flash, MiniMax M3, Qwen3.8 and Kimi K3, Together’s rate card matched the maker’s own. It is not a discount host.
- It was the fastest host for all six models. The gaps were large: GLM-5.3 took 2.80 seconds on Together against 5.36 on Z.ai, and Qwen3.8 took 2.95 against 11.46 on Novita.
- Caching depends on the model. Together’s automatic caching halved our DeepSeek bill. It never hit on GLM-5.3 Flash, and Llama 3.3 70B has no cached rate at all.
- Dedicated endpoints don’t make sense for a typical site. One H100 at $5.49 an hour is about $4,008 a month. On Together’s serverless DeepSeek, that money buys around 5.5 million chatbot answers.
Together AI pricing in October 2026
These are the serverless rates from Together AI’s pricing page, read on 19 October 2026, alongside the model maker’s own price where there is one. All prices are per million tokens. The “cheapest host” column is the lowest-priced endpoint OpenRouter listed for the same model that day, so you can see how far Together sits from the floor.
| Model | Together input / 1M | Together cached / 1M | Together output / 1M | Maker’s own price | Cheapest host listed |
|---|---|---|---|---|---|
| DeepSeek V4.1 Flash | $0.30 | $0.006 | $1.20 | $0.30 / $1.20 (DeepSeek, peak hours) | $0.045 / $0.08 (fp4) |
| GLM-5.3 | $1.40 | $0.26 | $4.40 | $1.40 / $4.40 (Z.ai) | $0.04 / $6.00 (fp8) |
| GLM-5.3 Flash | $0.15 | $0.03 | $0.50 | $0.15 / $0.50 (Z.ai) | $0.039 / $0.20 (fp4) |
| MiniMax M3 | $0.30 | $0.06 | $1.20 | $0.30 / $1.20 (MiniMax) | $0.224 / $0.88 (fp8, flex) |
| Qwen3.8 (2.4T-A95B) | $2.00 | $0.25 | $6.00 | $2.00 / $6.00 (Alibaba) | $2.00 / $6.00 |
| Kimi K3 | $3.00 | $0.30 | $15.00 | $3.00 / $15.00 (Moonshot) | $0.217 / $16.00 (mxfp4) |
| gpt-oss-120b | $0.15 | not listed | $0.60 | open weights, no maker API | $0.03 / $0.15 |
| Llama 3.3 70B | $1.04 | not listed | $1.04 | open weights, no maker API | $0.10 / $0.32 (fp8) |
Three things in that table are worth knowing before you pick a host.
Together matches the maker, not the market. For the newer models, Together’s price is identical to the price on the model maker’s own API. That makes Together a fair choice if you want a single US-based account for many models. It is not where you go to undercut the rate card. Other hosts on OpenRouter sold the same weights for much less, usually quantized to fp8 or fp4.
DeepSeek’s own API is cheaper half the day. DeepSeek charges $0.30 / $1.20 at peak and half that off-peak. Together charges the peak rate around the clock. We covered DeepSeek’s time-of-day pricing in our DeepSeek peak-hours analysis and the current Flash model in our DeepSeek V4.1 Flash pricing test.
Older models are where Together costs the most. Llama 3.3 70B at $1.04 for both input and output is a legacy price. Hosts that run it in fp8 charge a tenth of that. The newer models in this table, priced to match their makers, are a fairer deal.
Together also sells dedicated endpoints by the GPU-hour: $5.49 for an NVIDIA HGX H100 and $8.99 for a B200, on demand. Its GPU Clusters product lists the H100 at $3.99 an hour. The pricing page also has a Batch API column, but batch jobs return results hours later, so they are no use for live chat.
How we tested Together AI pricing on a chatbot
We used the same method as our other API pricing tests, so the numbers can be compared across posts. Every request had the same shape a production MxChat chatbot sends:
- System prompt: the chatbot instructions from mxchat.ai, unchanged.
- Retrieved context: four 4 KB excerpts from our own documentation and blog posts, chosen for each question the way the knowledge base retrieves them. This makes each request about 4,100 to 4,250 tokens, depending on the model’s tokenizer.
- Three real support questions: whether MxChat works with WooCommerce order lookups, whether the knowledge base needs Pinecone, and whether a visitor can be handed to a human on Slack or Telegram.
Each question went to each route twice: 6 calls per route, 16 routes, 96 calls. Requests went from our WordPress server in the US through OpenRouter, streamed, with the provider pinned and fallbacks turned off, so each call hit only the host named. We passed no reasoning setting, so each model used its default. We recorded time to first word, time to the complete answer, input, output and reasoning tokens, cached tokens, and the cost OpenRouter billed.
Together’s prices on OpenRouter matched Together’s own pricing page to the cent for every model we tested, so these figures carry over to a direct Together account.
The no-cache figure is what each answer costs if nothing is cached: tokens times the host’s list rate. The billed figure is what we were actually charged, including automatic prompt caching. A chatbot repeats its system prompt on every message, so the billed figure is closer to what you will pay.
One route failed. MiniMax M3 on DeepInfra returned HTTP 429, “temporarily rate-limited upstream”, on all six calls and every retry, so it is not in the results. That leaves 90 answered calls on 15 routes.
Results: cost per 1,000 chatbot answers
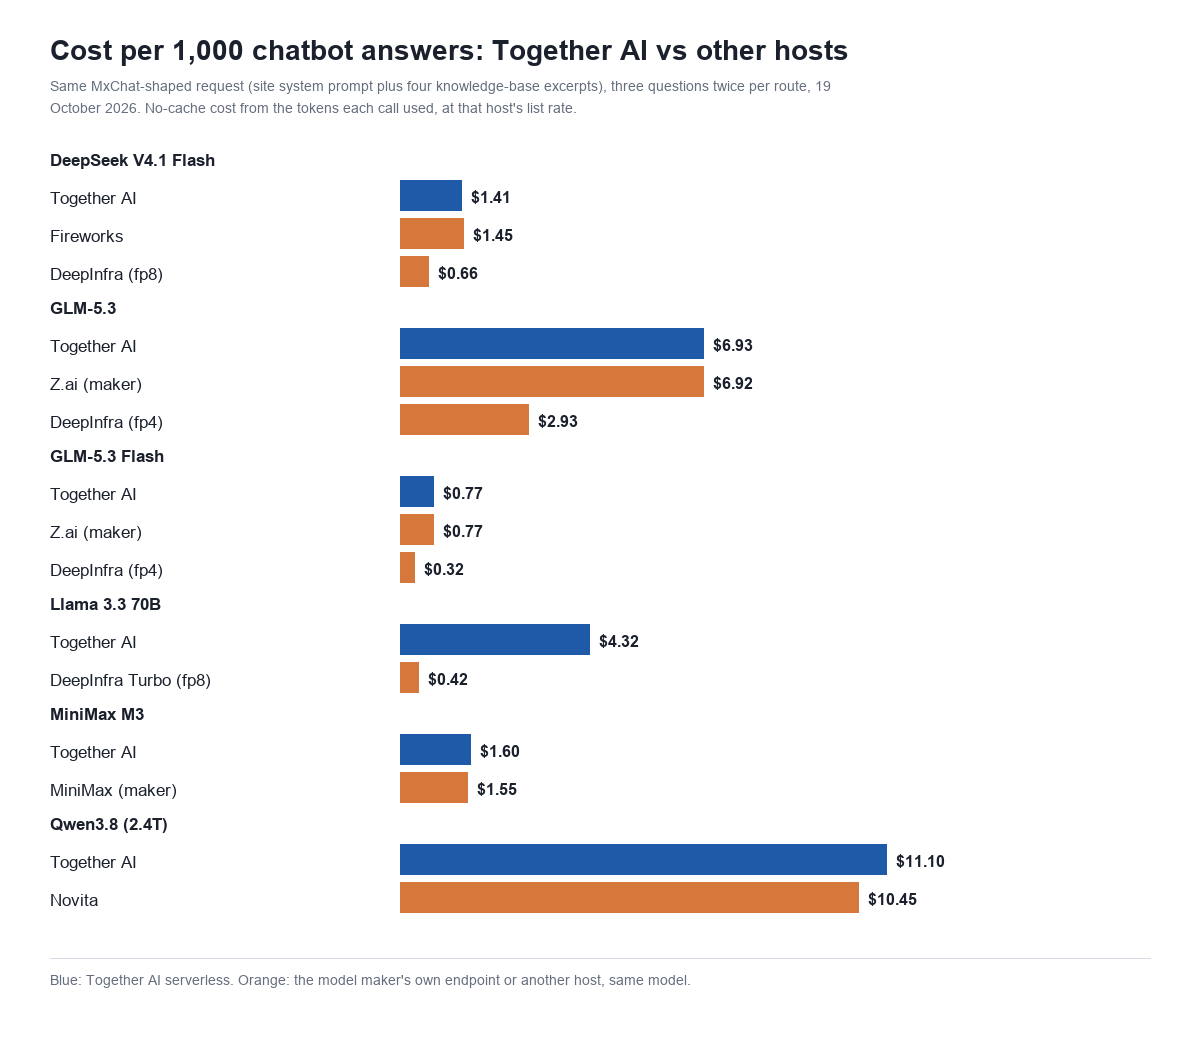
| Model and host | Input tokens | Output (of which reasoning) | No cache, per 1k | Billed, per 1k | Median answer |
|---|---|---|---|---|---|
| DeepSeek V4.1 Flash, Together | 4,204 | 125 (31) | $1.41 | $0.73 | 0.76 s |
| DeepSeek V4.1 Flash, Fireworks | 4,204 | 159 (65) | $1.45 | $0.79 | 2.36 s |
| DeepSeek V4.1 Flash, DeepInfra fp8 | 4,204 | 160 (73) | $0.66 | $0.34 | 2.12 s |
| GLM-5.3, Together | 4,121 | 263 (208) | $6.93 | $4.64 | 2.80 s |
| GLM-5.3, Z.ai | 4,121 | 260 (204) | $6.92 | $4.58 | 5.36 s |
| GLM-5.3, DeepInfra fp4 | 4,121 | 244 (179) | $2.93 | $1.94 | 4.01 s |
| GLM-5.3 Flash, Together | 4,121 | 295 (222) | $0.77 | $0.77 | 2.33 s |
| GLM-5.3 Flash, Z.ai | 4,121 | 308 (234) | $0.77 | $0.58 | 3.26 s |
| GLM-5.3 Flash, DeepInfra fp4 | 4,121 | 61 (0) | $0.32 | $0.29 | 5.19 s |
| Llama 3.3 70B, Together | 4,111 | 43 (0) | $4.32 | $4.32 | 1.63 s |
| Llama 3.3 70B, DeepInfra Turbo fp8 | 4,111 | 32 (0) | $0.42 | $0.42 | 4.22 s |
| MiniMax M3, Together | 4,252 | 268 (180) | $1.60 | $1.02 | 3.08 s |
| MiniMax M3, MiniMax | 4,252 | 232 (95) | $1.55 | $1.36 | 3.78 s |
| Qwen3.8, Together | 4,216 | 444 (387) | $11.10 | $7.49 | 2.95 s |
| Qwen3.8, Novita | 4,216 | 337 (284) | $10.45 | $7.13 | 11.46 s |
Where Together and another host charge the same rate, the bills came out within a few percent of each other. Most of the remaining gap came from the model thinking more or less on a given host. Qwen3.8 spent 387 reasoning tokens per answer on Together against 284 on Novita, which is why Together cost slightly more at the same price per token.
Where the rates differ, the rate decides. DeepInfra’s fp8 DeepSeek V4.1 Flash costs less than half of Together’s per token, and it billed less than half per answer. Its fp4 GLM-5.3 cost $1.94 per 1,000 answers against $4.64 on Together and $4.58 on Z.ai.
Two earlier tests used the same request, and Together sits in the same place in both. In our Kimi K3 host comparison, Together at the maker’s $3 / $15 came to $19.24 per 1,000 answers, against $7.93 on the cheapest host. In our Groq and Cerebras speed test, gpt-oss-120b on Together cost $0.75 per 1,000 answers and took 1.65 seconds, mid-pack on both.
Results: speed
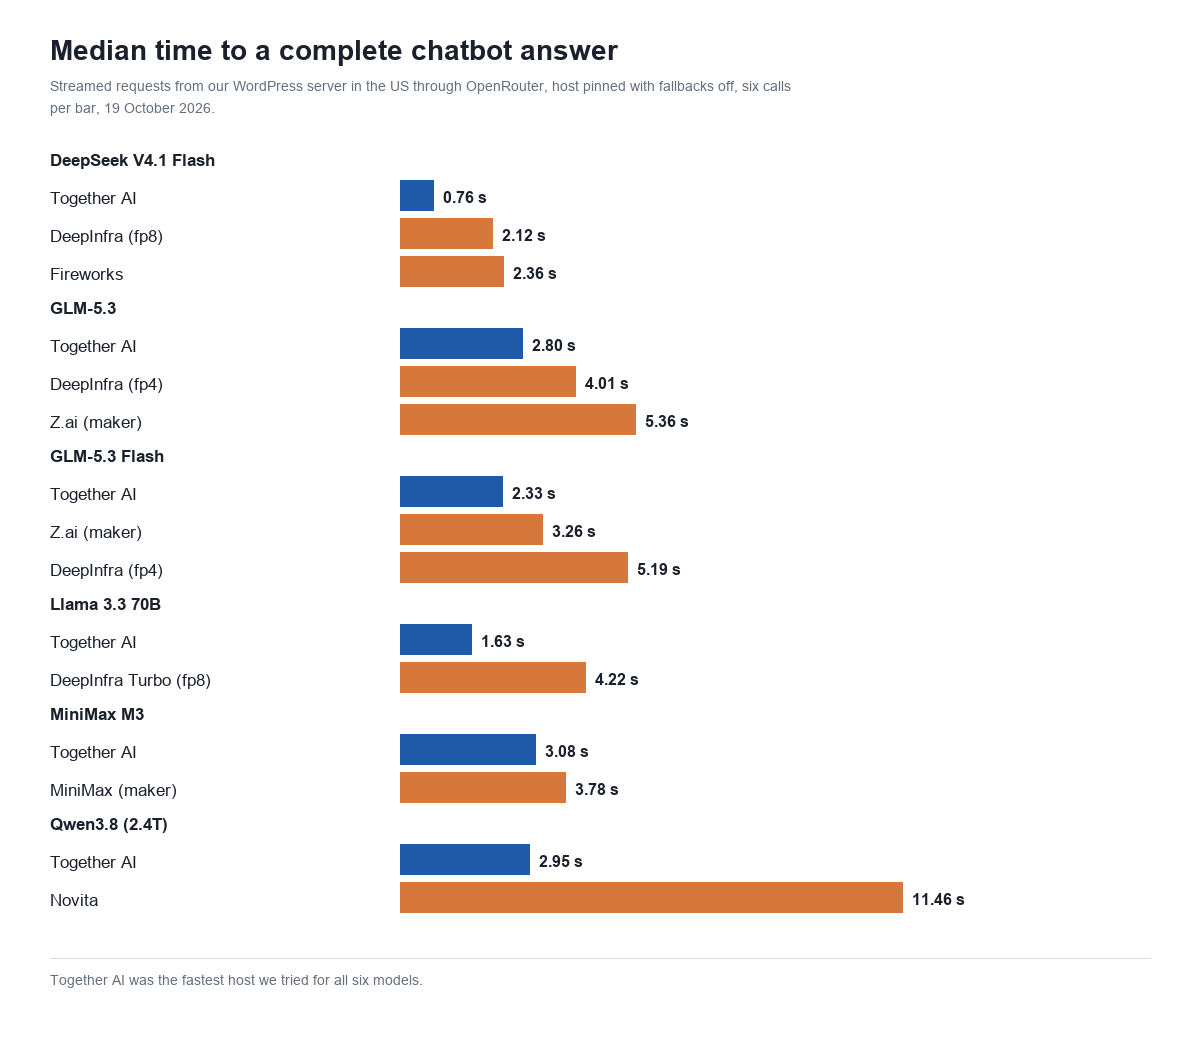
This is where Together earns its price. For every model we tested, Together returned the complete answer faster than any other host we tried, and usually by a wide margin:
- DeepSeek V4.1 Flash: 0.76 seconds on Together, first word after 0.38 seconds. DeepInfra took 2.12 seconds and Fireworks 2.36, at the same or lower price.
- GLM-5.3: 2.80 seconds on Together against 5.36 on Z.ai’s own endpoint, at an identical price. If you are paying Z.ai’s rate anyway, Together got the same answer in about half the time.
- Qwen3.8: 2.95 seconds on Together against 11.46 on Novita. Eleven seconds is too long for a chat window, and the two hosts charge the same.
- Llama 3.3 70B: 1.63 seconds on Together against 4.22 on DeepInfra Turbo. This is the one case where the speed costs real money: ten times the bill for 2.6 seconds back.
On a website chatbot, the wait for the complete answer is what the visitor experiences. Much of it is hidden reasoning. GLM-5.3 Flash spent around 220 reasoning tokens before writing a 50-word reply. A fast host gets through that before the visitor notices.
Results: caching
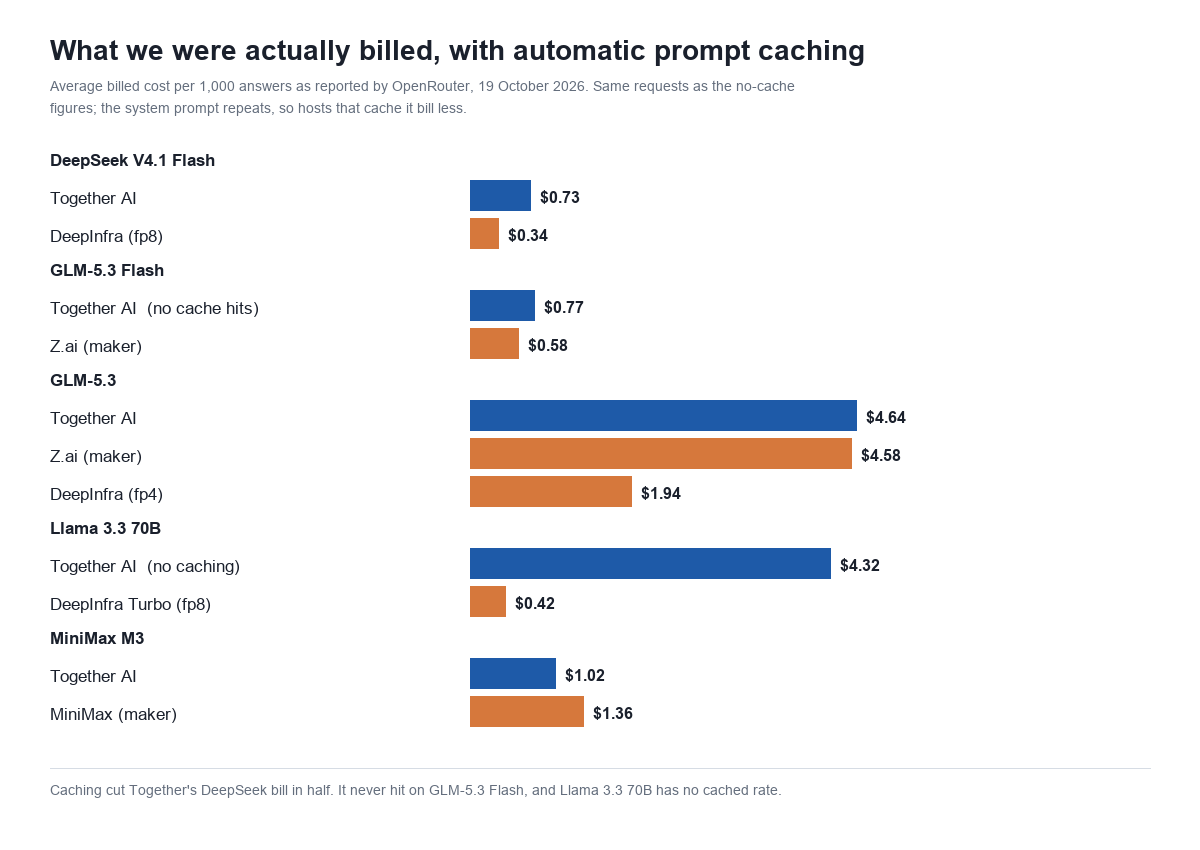
Together caches prompt prefixes automatically on models that list a cached rate. You do not add cache markers. How much that saved depended on the model:
- DeepSeek V4.1 Flash: Together read about 2,300 of the 4,200 input tokens from cache on average. At $0.006 per million for cached input, that halved the bill from $1.41 to $0.73 per 1,000 answers.
- MiniMax M3: caching worked better on Together than on MiniMax’s own endpoint (2,411 cached tokens against 806). Together came out cheaper as billed, $1.02 against $1.36, though the list price is the same.
- GLM-5.3 Flash: zero cache hits on Together across all six calls, so it billed the full $0.77. Z.ai’s own endpoint cached and billed $0.58.
- Llama 3.3 70B and gpt-oss-120b: no cached rate on Together’s price list, so there is nothing to save.
Caching only applies when the start of the prompt is the same each time, which is why a chatbot’s fixed system prompt benefits. The retrieved knowledge-base text changes with each question, so it is never cached. We go into this in more detail in our prompt-caching cost test.
Answer quality
All 90 answers were correct on the facts. The differences were in style and small slips:
- Llama 3.3 70B gave the shortest answers, 24 to 31 words on average, and hedged on the Pinecone question (“either WordPress or Pinecone”) where the newer models said plainly that Pinecone is optional.
- GLM-5.3 Flash on DeepInfra ran without reasoning (0 reasoning tokens) and was the cheapest route in the test at $0.29 per 1,000 answers. It once said Slack gives each visitor their own channel. That is true of Telegram, not Slack.
- GLM-5.3 on DeepInfra once linked to a pricing URL that does not exist on our site, and GLM-5.3 Flash on Together once misspelled the product name. Both were one-offs in six calls.
- MiniMax M3 wrote the longest answers, 85 words on average on MiniMax’s own endpoint, with bullet lists.
Host choice did not change correctness on these questions. It changed cost and speed.
What Together AI costs per month for a chatbot
Using the billed cost per 1,000 answers from our test, with automatic caching included:
| Model and host | 5,000 answers / month | 20,000 answers / month | 100,000 answers / month |
|---|---|---|---|
| DeepSeek V4.1 Flash, Together | $3.65 | $14.60 | $73.00 |
| DeepSeek V4.1 Flash, DeepInfra | $1.70 | $6.80 | $34.00 |
| MiniMax M3, Together | $5.10 | $20.40 | $102.00 |
| Llama 3.3 70B, Together | $21.60 | $86.40 | $432.00 |
| Llama 3.3 70B, DeepInfra Turbo | $2.10 | $8.40 | $42.00 |
| GLM-5.3, Together | $23.20 | $92.80 | $464.00 |
| GLM-5.3, DeepInfra | $9.70 | $38.80 | $194.00 |
| Qwen3.8, Together | $37.45 | $149.80 | $749.00 |
A typical small business site handles a few thousand chatbot answers a month. At that size, the difference between Together and the cheapest host is a few dollars, and Together’s speed is probably worth it. At 100,000 answers a month on GLM-5.3, the same difference is $270 a month.
Serverless vs a dedicated endpoint
A dedicated H100 on Together costs $5.49 an hour, or about $4,008 a month if left running. That buys roughly 5.5 million DeepSeek V4.1 Flash answers on Together’s serverless API at our billed rate, or about 860,000 GLM-5.3 answers. The larger models in this test also need more than one GPU to run. Unless your chatbot handles millions of conversations a month or you need a fine-tuned model of your own, serverless is the cheaper option.
When Together AI is worth it
| If you want | Use | Why |
|---|---|---|
| The fastest answers from an open model | Together AI | Fastest host for all six models we tested, at the maker’s price on five of them |
| The maker’s own model, faster | Together instead of Z.ai, MiniMax or Novita | Same price per token, up to four times faster in our test |
| The lowest bill on an open model | A quantized host such as DeepInfra | Half the cost or less, at two to four seconds per answer |
| Llama 3.3 70B | Not Together | Ten times the cost of fp8 hosts; a newer model on Together costs less and answers better |
| Off-peak DeepSeek pricing | DeepSeek’s own API | Half price outside peak hours; Together charges the peak rate all day |
| A very large, steady volume | Dedicated endpoint | Only past millions of answers a month |
How to use Together AI models with a WordPress chatbot
The simplest way to try these models on a WordPress site is through OpenRouter, which is how we ran this test. MxChat supports OpenRouter as a model provider, so you can pick any of these models from your chatbot settings with one API key. OpenRouter routes each request to a host. Unless you tell it otherwise it may not choose Together. OpenRouter’s account settings let you set provider preferences, so you can prefer the fast host or the cheap one. We compared OpenRouter’s costs against direct APIs in our OpenRouter pricing test.
Setup is covered in the MxChat core documentation. The WooCommerce order lookup, Pinecone-free knowledge base and Slack and Telegram handoff in our test questions are all real MxChat features, and MxChat Pro adds the WooCommerce integration and other add-ons.
If you are comparing hosts for a single model, our earlier host tests use the same request: GLM-5.3 across hosts, Kimi K3 across hosts and Qwen API pricing.
Frequently asked questions
How much does Together AI cost?
Together AI charges per token for serverless models. On 19 October 2026, DeepSeek V4.1 Flash was $0.30 per million input tokens and $1.20 output, GLM-5.3 was $1.40 and $4.40, MiniMax M3 $0.30 and $1.20, Kimi K3 $3.00 and $15.00, and Llama 3.3 70B $1.04 for both. In our WordPress chatbot test, 1,000 answers cost $0.73 on DeepSeek V4.1 Flash and $4.64 on GLM-5.3 as billed, with caching.
Is Together AI cheaper than the model maker’s API?
No. For the models we checked, Together’s per-token price was the same as the maker’s own: DeepSeek, Z.ai, MiniMax, Alibaba and Moonshot. DeepSeek’s own API is cheaper outside peak hours. Together was faster than the maker’s endpoint in every case we tested.
Is Together AI cheaper than DeepInfra?
Usually not. DeepInfra runs many models quantized to fp8 or fp4 at lower prices. In our test, DeepSeek V4.1 Flash cost $0.34 per 1,000 answers on DeepInfra against $0.73 on Together, and Llama 3.3 70B cost $0.42 against $4.32. Together was two to three times faster on both.
Does Together AI have prompt caching?
Yes, automatically, on models with a cached input rate on its pricing page. In our test it halved the DeepSeek V4.1 Flash bill and cut MiniMax M3 by about a third. It never hit on GLM-5.3 Flash. Llama 3.3 70B and gpt-oss-120b have no cached rate.
How much is a Together AI dedicated endpoint?
On 19 October 2026, an on-demand NVIDIA HGX H100 was $5.49 per GPU-hour and a B200 $8.99. Running one H100 all month costs about $4,008. Reserved pricing is by quote.
Which Together AI model is best for a website chatbot?
In our test, DeepSeek V4.1 Flash was the best value on Together: $0.73 per 1,000 answers as billed, under a second per answer, and correct on every question. GLM-5.3 Flash cost about the same per answer. Llama 3.3 70B was the worst value on Together at $4.32 per 1,000 answers.


